Most of your AI work doesn't need a frontier model
80–90% of your AI tasks don't need a frontier model. Smart routing saves real money without cutting quality, but someone has to own the decision.
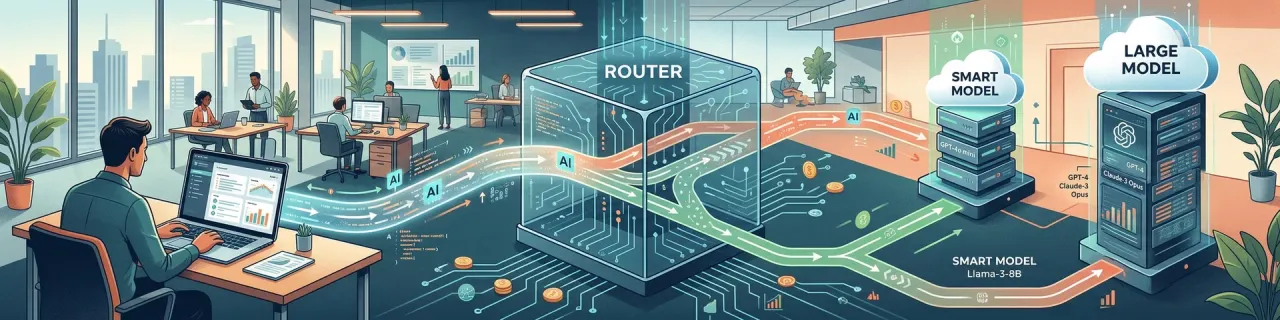
Here is a number that should bother every SMB leader paying for AI: somewhere between 80 and 90 per cent of the tasks your team runs through AI do not need a frontier model.
Not a rough guess. Think about what your people actually do with it day to day — summaries, extraction, reformatting, first-pass drafts, classification, inbox triage, meeting notes. None of that requires the most powerful model on the market. Most of it runs perfectly well on the cheapest one.
Yet the default in most small businesses is one model for everything. Usually the most expensive one, because that is what the AI-enthusiast on the team recommended and nobody questioned it.
That is not a technology problem. It is a management failure.
The cost gap nobody is explaining
The pricing spread between model tiers is not marginal. Taking Anthropic's current lineup as an example: Haiku — the lightweight model — costs a fraction of what Opus — the flagship — charges per million tokens. The output token price alone can differ by a factor of five or more. Other providers show similar gaps.
At low usage that barely registers. But once a team of five or ten people is running dozens of AI calls per day — and in an AI-fluent SMB, that happens fast — the difference compounds into real money.
The problem is that the people who understand this pricing structure are rarely the people making budget decisions. The developer or AI lead picks the model. The MD sees a monthly bill. Nobody connects the two. The AI enthusiasts inside your business are not hiding the cost from you — they just never think to explain it, because to them the model choice feels like a technical detail. To your P&L it is not a detail at all.
What model routing actually means
Routing is a simple idea: instead of sending every task to the same model, you match each task to the cheapest model that still delivers acceptable quality.
In practice, most AI work falls into three lanes. The first is low-cost work — extraction, summaries, formatting, categorisation, and anything where the output is either right or wrong with little room for interpretation. A lightweight model like Haiku handles this comfortably. The second is mid-tier work — first-pass synthesis, structured drafts, and tasks that need some interpretive judgement but are not client-facing or high-stakes. A balanced model like Sonnet fits here. The third is high-capability work — final client deliverables, nuanced strategic analysis, complex reasoning, and anything that touches money, commitments, or legal exposure. This is where you use the frontier model, and this is where it earns its price.
The critical point is that the third lane should be the smallest. If your team is routing more than 10 to 20 per cent of its work to the most expensive model, the lanes are miscalibrated.
You do not have to do this manually
The earliest version of routing is a simple policy: a one-page document that tells the team which lane each recurring task belongs in. That works, but it depends on humans remembering the rules — and in practice, within a week, the team drifts back to one model for everything.
The better approach is to automate the decision. There are several ways to do this, depending on how technical your setup is.
A proxy-based model router sits between your team and the AI provider. It classifies each request — by keyword, message length, context size, or task type — and routes it to the appropriate model automatically. I built one of these for my own workflow. It uses a simple rule-based classifier: short, low-complexity messages go to Haiku, tool-heavy or standard work goes to Sonnet, and only complex reasoning or large-context tasks escalate to Opus. There is a manual override for when you know you need the top tier — and a JSONL log so you can audit what went where and why.
If you do not want to build your own, services like OpenRouter provide this as a managed layer. OpenRouter gives you a single API endpoint that routes to hundreds of models across providers. Their auto-router analyses each prompt and selects the optimal model based on complexity, task type, and your preferences. You can also set explicit routing rules — price-first, latency-first, or restrict to specific model families. The point is that routing becomes infrastructure, not willpower.
Even at the simplest level, a well-configured proxy means your team does not have to think about model selection at all. The routing logic handles it. The humans focus on the work.
Where this pays off fastest
Three areas tend to show returns within the first week.
Internal communication cleanup is the most obvious. Long email threads, Slack channels, meeting transcripts — summarisation and action extraction are high-volume, low-judgement tasks. A cheap model handles them cleanly. You only escalate when the summary needs to capture political nuance or ambiguous commitments, which is rare.
Operational reporting is the next win. First-pass data prep, narrative scaffolding, and template population are all mid-tier work at most. The expensive model only needs to appear at the interpretation layer — the paragraph that says here is what this means and what we should do about it.
Client deliverables are where routing discipline matters most. Final client-facing outputs stay in the high-capability lane with named human ownership. Everything upstream — the drafting, the research assembly, the formatting — can run cheaper.
Why this fails without ownership
I wrote recently about why teams stop using AI tools despite having access to good ones. The pattern is the same here. Routing fails when nobody owns it.
You need three things. An owner — one person accountable for routing decisions and exceptions. An escalation rule — a single sentence defining when work must move to the high-capability lane. And a weekly review — 15 minutes, same day each week, looking at cost per task and rework rate.
Without all three, the team reverts to default behaviour within days. With all three, you have a lightweight operating rhythm that compounds savings every week.
A week to prove it
Pick two or three recurring workflows. Assign each to a lane. Define the escalation trigger. Run real work through the lanes for five days and log every exception — what got escalated, why, and whether the lower-tier output was actually insufficient or just unfamiliar.
On day six, review cost per task and rework rate. Keep what cut cost without creating rework. Drop what added friction. Document the surviving routes as your new default.
The goal is not theoretical optimisation. The goal is predictable quality at predictable cost — and evidence you can show your MD that the AI budget is being managed, not just spent.
Model choice is a technical decision. Model routing is a management decision. For most SMBs, that distinction is where the savings are — and right now, almost nobody is making it.